The Needle in the Chatbot Haystack
When The New York Times sued Microsoft and OpenAI for copyright infringement, the mental image it painted for the public was striking: a rogue AI vacuuming up...
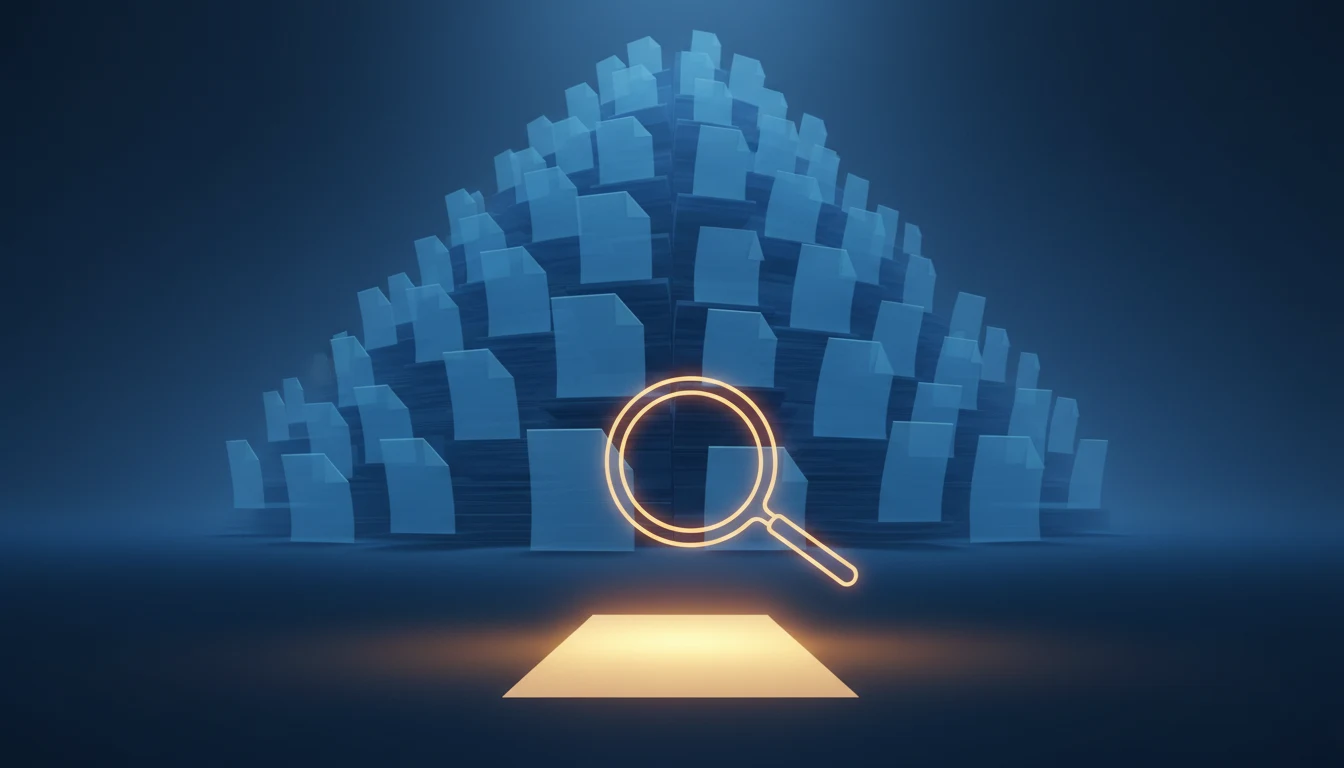
When The New York Times sued Microsoft and OpenAI for copyright infringement, the mental image it painted for the public was striking: a rogue AI vacuuming up journalistic hard work and spitting it back out to users for free. But as the legal battle intensifies, Microsoft is trying to puncture that narrative with cold, hard data.
In recent legal filings, Microsoft presented what essentially amounts to a "needle in a haystack" defense. During the discovery phase of the lawsuit, the tech giant handed over 8.2 million Copilot chat logs to an expert hired by the news publishers. Crucially, these weren't just random interactions pulled from the ether. They were specifically filtered using keywords tied to the plaintiffs' websites, meaning they represented the absolute highest risk of containing copied material.
The results of this targeted search? Out of those 8.2 million highly specific conversations, only about 59,000 logs showed any relevant overlap. Microsoft argues this proves that Copilot rarely reproduces full sentences from news articles or books, let alone substantive chunks that could serve as a viable substitute for the original reporting.
This brings us to the heart of the modern copyright dilemma: the concept of market substitution. If an AI chatbot regurgitates an article so thoroughly that a user no longer feels the need to visit the original publisher's website, that poses a direct economic threat to the creator. However, if the AI merely digests the information and synthesizes it—much like a human researcher or a student writing a book report—the legal waters become much murkier. Is the AI stealing, or is it simply learning?
For the average internet user, this lawsuit might seem like a clash of corporate titans, but its ripple effects will eventually touch everyone. It will dictate how AI tools are designed in the future. If courts rule that AI companies must pay licensing fees for every piece of content their models have ever ingested, the cost of these currently free or low-cost tools could skyrocket, or their capabilities could be severely nerfed. Conversely, if tech companies win outright, publishers might lock their content behind even stricter paywalls to prevent scraping, fundamentally altering how free information flows on the internet.
As this landmark case unfolds, it isn't just about whether a chatbot read a specific news story. It's about drawing a new legal boundary for the generative AI era, determining how digital labor is valued in a world where machines are constantly learning from everything we publish.
Key Points
- Microsoft argues Copilot rarely reproduces substantive chunks of copyrighted news or books.
- The company provided 8.2 million targeted chat logs to legal experts hired by the publishers.
- Only a tiny fraction of these high-risk logs (around 59,000) showed potential content overlap.
- The case hinges on whether AI outputs serve as an economic substitute for original journalism.
- The lawsuit's outcome could drastically alter how AI tools are built and how digital content is paywalled.
Why It Matters
The outcome of this lawsuit will redefine the legal boundaries of fair use in the generative AI era, impacting how digital content is valued and how accessible AI tools will be in the future.
Sources:
更多专栏
Your Next Coworker is a Blob That Orders Burritos
For decades, enterprise software has been synonymous with sterile dashboards, en...
The Midnight Bill: Why AI Agents Demand Hard Budget Caps
The dream of artificial intelligence is to have a tireless digital assistant wor...
Beyond Transformers: How Mamba is Rewriting the Rules of AI Memory
Think about how a human reads a sprawling, thousand-page fantasy series. You don...