The Music Industry's War on 'Model Laundering'
If you steal a secret recipe, bake a cake, and then write down a brand-new recipe based purely on how that cake tastes, is your new recipe stolen property?...
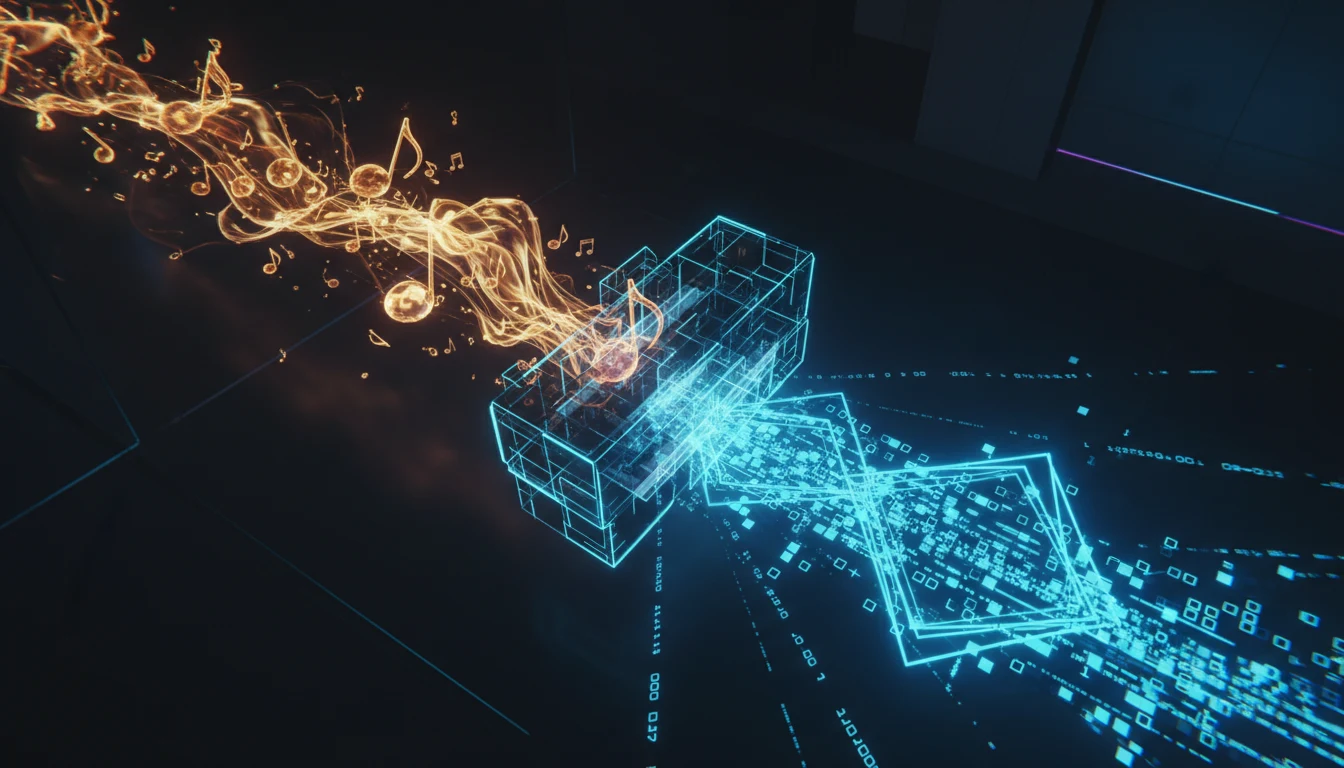
If you steal a secret recipe, bake a cake, and then write down a brand-new recipe based purely on how that cake tastes, is your new recipe stolen property? This kind of philosophical puzzle has officially entered the courtroom, as legacy music labels clash with the bleeding edge of artificial intelligence.
Sony and Universal Music Group (UMG) have launched yet another legal strike against Suno, one of the most prominent AI music generation platforms on the market. The target of this new lawsuit is Suno’s latest v6 model, and the accusation centers around a fascinating and contentious new term: "model laundering."
To understand the conflict, we have to look at how AI models evolve. Suno’s earlier models were accused of being trained on massive amounts of unlicensed, copyrighted music scraped from platforms like YouTube. To build their newer v6 model, Suno allegedly took a different route. Instead of feeding it raw, copyrighted human music, they trained it on the synthetic outputs—the AI-generated songs—produced by their older models.
From an engineering perspective, training AI on synthetic data is a common practice. It’s a way to refine outputs and, theoretically, distance a new model from the messy copyright issues of original human datasets. But Sony and UMG, who have notably refused to sign any licensing agreements with Suno, argue that this technological degree of separation is merely an illusion.
In their complaint, the record labels argue that training a new model on the outputs of an infringing model doesn't erase the original sin. Instead, it "launders" it. They claim this practice effectively passes the inherent value and creative expression of the original, stolen human music down the generational line, much like laundering dirty money through a shell company doesn't make the money legally earned.
This lawsuit represents a critical frontier in AI ethics and copyright law. As artificial intelligence companies increasingly turn to "AI training AI" to improve their systems and bypass depleted or legally restricted human data sources, the music industry is drawing a hard line in the sand.
If the courts side with Sony and UMG, validating the concept of "model laundering," it could send shockwaves far beyond the music industry. It would suggest that AI companies cannot simply use synthetic data as a legal firewall. The ghosts of the original training data may haunt these models for generations to come, forcing the tech industry to rethink how it builds the foundation of our automated future.
Key Points
- Sony and UMG have filed a new lawsuit against AI music startup Suno, focusing on its v6 model.
- The labels accuse Suno of 'model laundering'—training a new model on the AI-generated outputs of older, allegedly infringing models.
- Sony and UMG argue that using synthetic data derived from stolen copyrighted works does not erase the original infringement.
- The lawsuit challenges a common AI industry practice of using synthetic data to bypass copyright restrictions on raw data.
Why It Matters
The concept of 'model laundering' tests a major legal loophole in AI development. If courts rule that synthetic data inherits the copyright violations of its parent models, it could drastically alter how all generative AI systems are trained.
Sources:
- Sony and UMG are suing Suno again — The Verge - AI
更多专栏
Your Next Coworker is a Blob That Orders Burritos
For decades, enterprise software has been synonymous with sterile dashboards, en...
The Midnight Bill: Why AI Agents Demand Hard Budget Caps
The dream of artificial intelligence is to have a tireless digital assistant wor...
Beyond Transformers: How Mamba is Rewriting the Rules of AI Memory
Think about how a human reads a sprawling, thousand-page fantasy series. You don...