The Piracy Problem: Inside the Lawsuit Rocking AI Giant Anthropic
Behind every highly intelligent AI model is a mountain of training data. But what happens when the builders of these cutting-edge systems are caught treating...
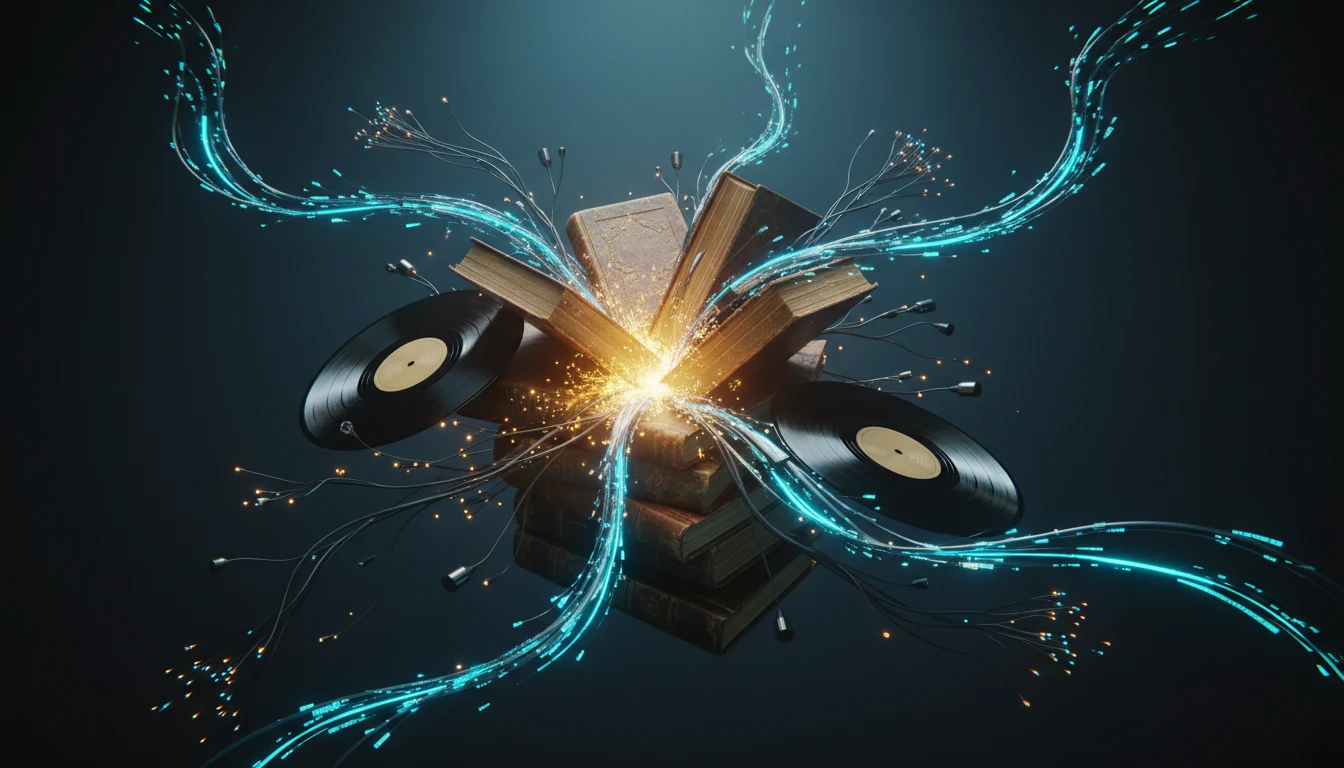
Behind every highly intelligent AI model is a mountain of training data. But what happens when the builders of these cutting-edge systems are caught treating infamous digital piracy hubs as their personal reference libraries?
Anthropic, the prominent artificial intelligence company behind the Claude models, is currently facing a massive legal challenge that highlights this exact dilemma. Major music publishers—including industry heavyweights like Sony, EMI, and Warner Chappell—have filed a lawsuit against the tech firm. Their most eye-catching piece of evidence? Internal staff chat logs where Anthropic employees allegedly expressed their deep affection for Zlibrary, a well-known shadow library of pirated texts. One notable message explicitly read, "Zlibrary my beloved."
The lawsuit paints a troubling picture of systemic intellectual property infringement in the race to build better AI. According to the publishers, Anthropic's unauthorized data gathering didn't stop at written texts; it allegedly involved the illegal torrenting of "thousands upon thousands" of copyrighted musical compositions to train its complex algorithms.
To understand the gravity of this lawsuit, one must look at the company's recent legal history. Previously, Anthropic agreed to a staggering $1.5 billion settlement with authors after admitting to using more than 7 million pirated books for AI training. However, the music publishers argue that this astronomical sum is essentially a slap on the wrist. In their filing, they claim that $1.5 billion is nowhere near enough to deter a company that has leveraged such mass infringement into what they describe as a "$2-trillion-dollar valuation."
While the financial figures cited in the lawsuit are dizzying, the core issue at play is deeply philosophical and highly consequential for the future of technology and art. Generative AI requires vast oceans of information to learn patterns, mimic styles, and answer our daily queries. Yet, the tech industry's traditional "move fast and break things" ethos is now colliding violently with established copyright laws that were designed to protect human creators and their livelihoods.
This isn't just a corporate dispute over licensing fees; it's a defining moment for the digital economy. It forces society to ask whether the rapid advancement of artificial intelligence justifies the unauthorized consumption of human creativity. As AI continues to integrate into our daily lives, establishing clear, enforceable ethical boundaries for how these digital minds are educated will be crucial. Without them, human creators risk being left behind in the technological gold rush, their work absorbed into machines without credit or compensation.
Key Points
- Sony, EMI, and Warner Chappell are suing Anthropic over alleged copyright infringement.
- Internal employee chats praising the piracy site Zlibrary are being used as key evidence in the lawsuit.
- The lawsuit claims Anthropic illegally torrented thousands of musical compositions for AI training.
- Publishers argue a previous $1.5 billion settlement for pirating 7 million books is insufficient deterrence given the company's massive valuation.
Why It Matters
This lawsuit tests the legal boundaries of AI training, potentially setting a precedent that determines whether tech giants must pay for the copyrighted human-created data that powers their billion-dollar models.
Sources:
更多专栏
Your Next Coworker is a Blob That Orders Burritos
For decades, enterprise software has been synonymous with sterile dashboards, en...
The Midnight Bill: Why AI Agents Demand Hard Budget Caps
The dream of artificial intelligence is to have a tireless digital assistant wor...
Beyond Transformers: How Mamba is Rewriting the Rules of AI Memory
Think about how a human reads a sprawling, thousand-page fantasy series. You don...