The Trillion-Dollar Question: Is AI Training 'Fair Use'?
When an artificial intelligence reads millions of news articles to learn how to communicate, is it simply learning, or is it engaged in massive-scale theft?...
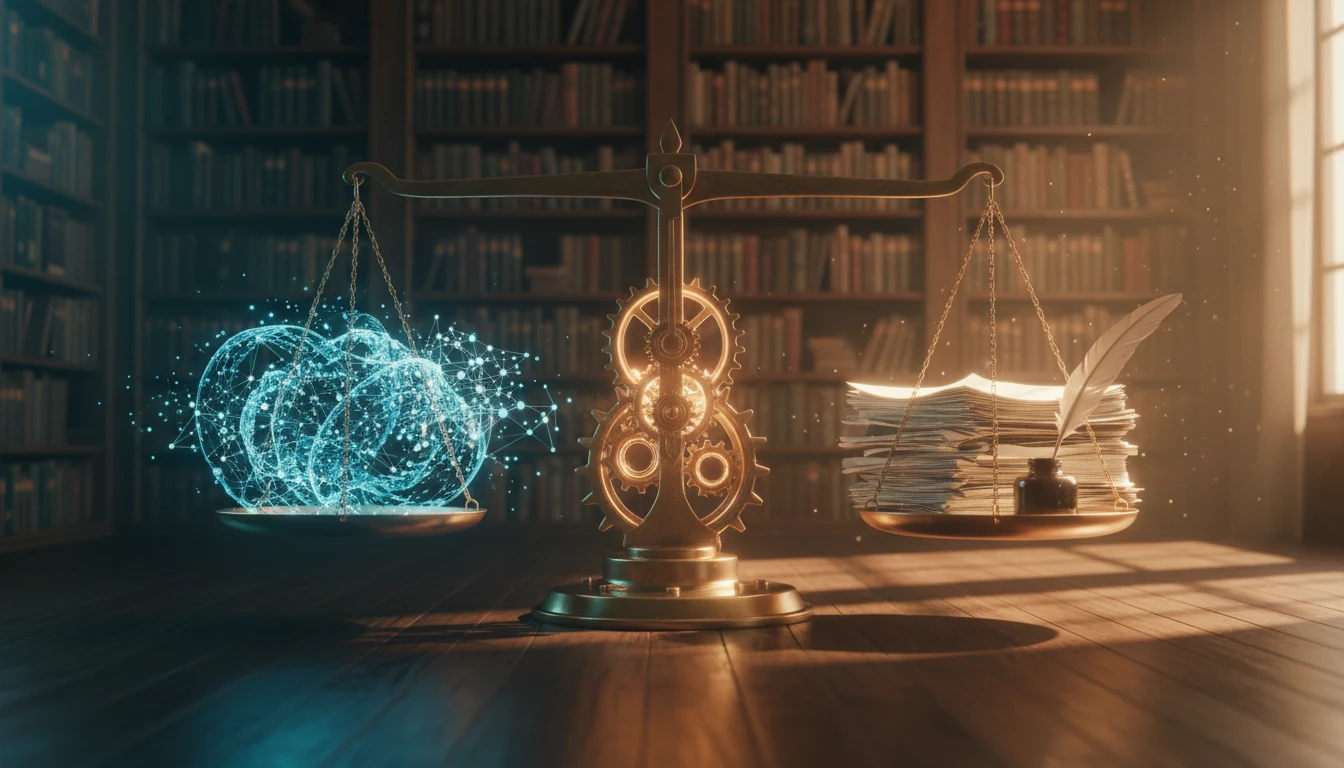
When an artificial intelligence reads millions of news articles to learn how to communicate, is it simply learning, or is it engaged in massive-scale theft? This modern philosophical question is at the heart of a multi-billion-dollar legal battle that just gained a powerful new participant: the United States government.
In December 2023, The New York Times launched a landmark lawsuit against OpenAI and its primary backer, Microsoft. The media giant claimed that the tech companies unlawfully ingested its copyrighted journalism to train Large Language Models (LLMs), demanding billions in damages for the unauthorized use of its intellectual property. Now, the Trump administration has officially weighed in, filing a "statement of interest" that throws the government's legal weight firmly behind OpenAI.
A statement of interest allows the government to express its views on private lawsuits that could significantly impact public policy or federal law. In this case, the debate hinges entirely on a foundational legal concept known as "fair use."
Traditionally, the fair use doctrine allows people to use copyrighted material under certain conditions without explicit permission—such as quoting a book for a critical review, using snippets for academic research, or parodying a famous song. OpenAI and its defenders argue that training an AI is essentially a high-tech, automated version of reading. They claim the machine analyzes the text to understand grammar, extract facts, and recognize linguistic patterns, rather than just memorizing and regurgitating the exact articles.
The administration’s recent filing supports this exact perspective. It argues that The New York Times is attempting to artificially narrow the definition of fair use to specifically exclude the training of large language models. From the government's viewpoint, restricting AI companies from analyzing publicly accessible text could stifle technological innovation.
This legal intervention is incredibly significant because the stakes extend far beyond a single newspaper or a single tech startup. The eventual court ruling will likely serve as the blueprint for how AI models are allowed to consume the internet.
If courts ultimately decide that AI training does not qualify as fair use, the foundational mechanics of the entire AI industry could be upended. Tech companies would likely need to negotiate complex, prohibitively expensive licensing deals for every piece of data they ingest. This could potentially freeze smaller, open-source developers out of the market entirely, leaving AI development only to the wealthiest corporations. Conversely, a definitive legal victory for OpenAI would solidify a protective shield for tech companies, allowing them to continue scraping the internet to build increasingly capable systems.
Ultimately, this lawsuit highlights a growing societal tension. As machines become increasingly reliant on high-quality, human-generated content to sound intelligent and accurate, the legal system is being forced to decide how to properly value—and compensate—the human creators who provide that foundational knowledge.
Key Points
- The New York Times sued OpenAI in 2023 for billions, alleging unauthorized use of copyrighted articles for AI training.
- The Trump administration filed a legal statement supporting OpenAI's 'fair use' defense.
- The government argues that NYT is attempting to improperly narrow the fair use doctrine to exclude AI training.
- The outcome of this case will set a precedent that could drastically alter the cost and legality of developing AI models.
Why It Matters
The legal definition of 'fair use' in the context of AI will dictate whether future AI development remains accessible to startups or becomes a luxury only affordable to tech giants who can pay for massive data licenses.
Sources:
更多专栏
Your Next Coworker is a Blob That Orders Burritos
For decades, enterprise software has been synonymous with sterile dashboards, en...
The Midnight Bill: Why AI Agents Demand Hard Budget Caps
The dream of artificial intelligence is to have a tireless digital assistant wor...
Beyond Transformers: How Mamba is Rewriting the Rules of AI Memory
Think about how a human reads a sprawling, thousand-page fantasy series. You don...